OAuth2 vs OpenID Connect Explained: Authorization vs Login
OAuth2 authorizes; OpenID Connect authenticates. If you are choosing between OAuth2 and OpenID Connect for a login button, you want OIDC. If your app only calls an API on a user's behalf, plain OAuth2 is enough.
I run identity for a large classifieds platform, so I see this confusion in real integrations: a team gets a valid access token and treats it as proof of login. It is not. This article explains the mechanism, the flow to pick, and the mistakes I would check first.
Key takeaways- OAuth2 issues access tokens so a client can call an API; it says nothing about who the user is. OIDC adds the ID token that does.- Addingscope=openidto an authorization request is what turns an OAuth2 request into an OIDC request.- Use authorization code with PKCE for users and client credentials for services; do not start new work on implicit or password grants.- Validate the ID token (signature,iss,aud,exp,nonce) and keep roles and permissions checks in your API.- Treat redirect URIs, token lifetimes and client configuration as reviewed code, not console clicks.
The direct answer: OAuth2 authorizes, OpenID Connect authenticates
OAuth2 (RFC 6749) is a framework for delegated access. The client gets an access token from the authorization server and uses it against a resource server. One explainer on OAuth2 versus OIDC puts the key point plainly: OAuth2 does not authenticate users, it only allows access to resources on their behalf. That is a single blog post, so treat it as a clear summary, not an authority. The RFC is the authority.
OpenID Connect 1.0 is, in the words of the OpenID Connect Dynamic Client Registration spec, a simple identity layer on top of OAuth 2.0. It lets clients verify the end user's identity based on authentication performed by an authorization server. It also lets them obtain basic profile information. In practice that means the ID token, the openid scope and the UserInfo endpoint.
The same explainer offers a useful picture: OAuth2 is a valet key, and OIDC confirms who is holding the key. A picture is not a security model, but it sticks.
Question | OAuth2 | OIDC | Where it misleads |
|---|---|---|---|
What does it give the client? | Access token | Access token plus ID token | An access token alone may be opaque; it need not describe the user |
Does it tell me who logged in? | No | Yes, via ID token claims | The ID token proves authentication at issue time, not current permissions |
Typical use | Call a calendar or storage API | "Log in with" buttons, SSO | SSO does not decide what the user may do in your app |
Practical rule: if the app needs a login session, you need OIDC; if it only calls an API, plain OAuth2 is enough.
How the mechanism differs: access tokens, ID tokens and scopes
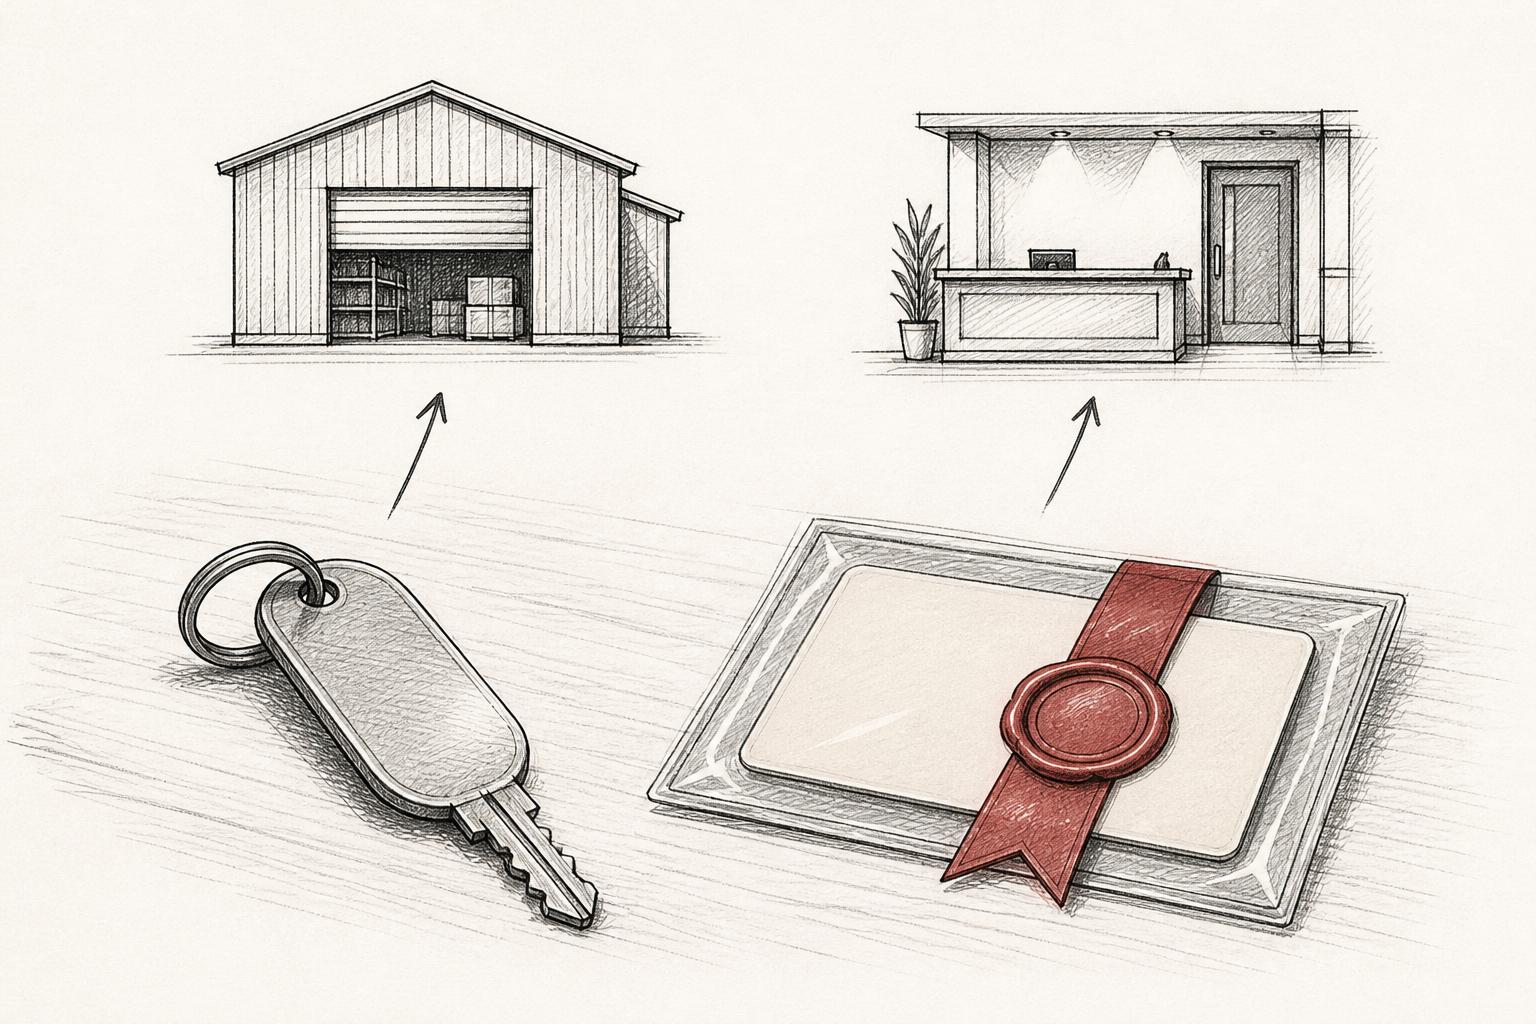
Two tokens, two audiences
The access token is meant for the resource server. It is often opaque, and the client should not parse it or build logic on its contents. Some providers issue JWT access tokens, but that is an implementation choice you cannot rely on across providers.
The ID token is a signed JWT meant for the client. It carries claims such as iss (who issued it), sub (the stable user identifier), aud (who it is for), exp, iat and nonce. The client reads it to establish a session. It should not forward it to an API as a bearer credential.
Scopes decide which protocol you are speaking
Adding scope=openid switches the request from OAuth2 to OIDC. After that, profile and email shape which claims come back. offline_access asks for a refresh token that outlives the browser session, which is convenient and also widens the damage of a leak. Request it only when a background job truly needs it.
Discovery and keys
OIDC providers publish metadata at /.well-known/openid-configuration. It lists the authorization, token and UserInfo endpoints and the JWKS location. Clients that read discovery and fetch signing keys from the JWKS endpoint avoid hardcoding URLs and survive key rotation. The cost is a dependency on that endpoint, so cache the keys and refresh on an unknown kid.
For Keycloak specifically, one set of reading notes on the Keycloak book shows the book separating discovery, the ID token and the UserInfo endpoint into the OIDC chapter. Access token validation sits in a separate OAuth 2.0 chapter. That split mirrors the protocol split.
Which flow to use: authorization code with PKCE, and what to retire
The default
Authorization code with PKCE is my default for web, mobile and single-page apps. The NHI Management Group guide covers grant types, client types and what OAuth 2.1 changes, and the OAuth 2.1 drafts make PKCE mandatory for the code flow. Drafts can change, so check the current text before you cite it in a design review. PKCE is worth using even for confidential clients, because it binds the code to the client that started the request.
What to retire
Implicit flow returns tokens in the redirect fragment. The OpenID Connect Implicit Client Implementer's Guide is a 2015 draft written for that flow, and I would treat it as history. The resource owner password grant has the client handle the user's password, which defeats the point of delegation. I would not start a new integration with either.
Machine-to-machine
Client credentials suits service calls. There is no user, so there is no ID token and no OIDC. The service authenticates as itself and gets an access token.
The browser trade-off
A single-page app is a public client. As a Keycloak forum answer puts it, you cannot safely store a secret in a front application. A backend-for-frontend keeps tokens out of browser storage and lets the backend be a confidential client. The trade-off is one more service to run, scale and secure. For a small internal tool, a public client with PKCE and short lifetimes may be the more honest choice.
Practical rule: authorization code with PKCE for anything with a user; client credentials for services; nothing else in new code.
When each applies, and when it does not
The classic mistake
Using OAuth2 alone for login is the classic mistake. A valid access token proves that a grant exists. It does not prove this user just authenticated, and it may have been issued to a different client entirely.
OIDC is not authorization
OIDC tells you who the user is. It does not tell you what they may do. Roles, permissions and tenant checks still belong to your API or a policy layer. Putting roles in the ID token is convenient, but the API must still enforce them.
An honest limitation
ID token claims are a snapshot. If a user's group or role changes, the claim may not change until the token is refreshed or the user logs in again. For high-risk actions, check current state server-side, or keep token lifetimes short enough that staleness is tolerable. Shorter lifetimes cost more refresh traffic.
Service-to-service
Internal traffic between services often needs only client credentials with short-lived tokens. Full OIDC adds ceremony without adding a user to identify. The exception is when a service acts on behalf of a user, where you need to propagate user context deliberately.
Worked example: a web app with login and an API call, in an identity provider like Keycloak
This is an example setup, not a prescription for your exact Keycloak version. Console labels vary by version, so check the official documentation.
Configure the client
- Register a confidential client, because this app has a backend that can keep a secret.
- Set exact redirect URIs, such as
https://app.example.com/callback. - Enable PKCE with the S256 method.
- Request
scope=openid profile emailplus one API scope, for exampleorders:read(an invented name for this example).
Walk the sequence
- The app redirects the browser to the authorization endpoint with the code challenge and a
nonce. - The user logs in at the identity provider.
- The provider redirects back with an authorization code.
- The backend exchanges the code at the token endpoint, sending the code verifier.
- The response contains an ID token for the session and an access token for the API.
Validate the ID token
- Verify the signature using keys from the JWKS endpoint.
- Check
issmatches your provider. - Check
audequals your client ID. - Check
exphas not passed. - Check
noncematches the value stored in the session.
The API separately checks the access token's audience and scope. Different token, different checks.
Keep it in code
I manage identity as code with Keycloak and Terraform, so clients, scopes and mappers change through reviewed pull requests rather than console clicks. The payoff is a diff you can read and a rollback you can run. If you would rather not operate the server, managed options exist, including RealmDeploy, a managed Keycloak on Kubernetes offering that is listed as coming soon. You can read my background running platform, security and identity and see side projects including managed Keycloak.
Practical rule: validate the ID token in the client and the access token in the API; never swap them.
Common failures I would check first
Loose redirect URIs
Wildcard or prefix-matched redirect URIs enable code interception. Require exact string matches. A Keycloak OIDC overview lists mismatched redirect URIs, stale client secrets and clock drift among the common tripwires. That is a vendor blog, so read it as a practitioner's list and not data. Clock drift is real, though: keep servers on NTP, or exp and iat checks will fail in confusing ways.
Skipping aud and iss
If you skip these checks, a token minted for another client can be accepted by yours. The IETF's JWT client authentication update draft exists to tighten audience requirements after a vulnerability was found in how audience values were specified. It is a work-in-progress draft, so cite it as that. It still shows that audience handling is a place where real specifications went wrong.
Long-lived tokens
Long-lived access tokens, and refresh tokens without rotation, widen the blast radius of a leak. Shorten access token lifetimes, rotate refresh tokens, and test that logout and revocation actually stop access. Test it; do not assume it.
Starter kits
If you are building a SaaS, a starter such as MakeV1: Ship your SaaS with the hard parts already done. can handle auth plumbing. Still review its token validation yourself, against the checks above. That advice applies to any starter, library or framework.
Further reading is in more engineering notes.
Run this checklist for every OAuth2 or OIDC integration
- Decide the need. API access only means OAuth2. User login too means OIDC with
scope=openid. - Pick the flow. Authorization code with PKCE for users, client credentials for services. No implicit or password grants.
- Lock the client. Exact redirect URIs, minimal scopes, and a confidential client wherever a backend exists.
- Validate tokens. Signature,
iss,aud,expandnoncefor ID tokens; audience and scope checks in the API. - Shorten lifetimes and rotate refresh tokens. Then test logout and revocation end to end.
- Put the configuration in version control. Review client, scope and mapper changes like code.